|
I am an undergraduate student at the Huazhong University of Science and Technology (HUST). I will join the Chinese University of Hong Kong, Shenzhen (CUHK-Shenzhen) as an incoming PhD student, advised by Prof. Li Jiang. My research interests include visual tokenizers, video generation, unified multimodal understanding and generation, and embodied intelligence. I have been fortunate to work with Prof. Xiang Bai and Prof. Yuliang Liu at the VLR Lab, and Prof. Wei Wei at the CCIIP Lab at HUST. |
|
|
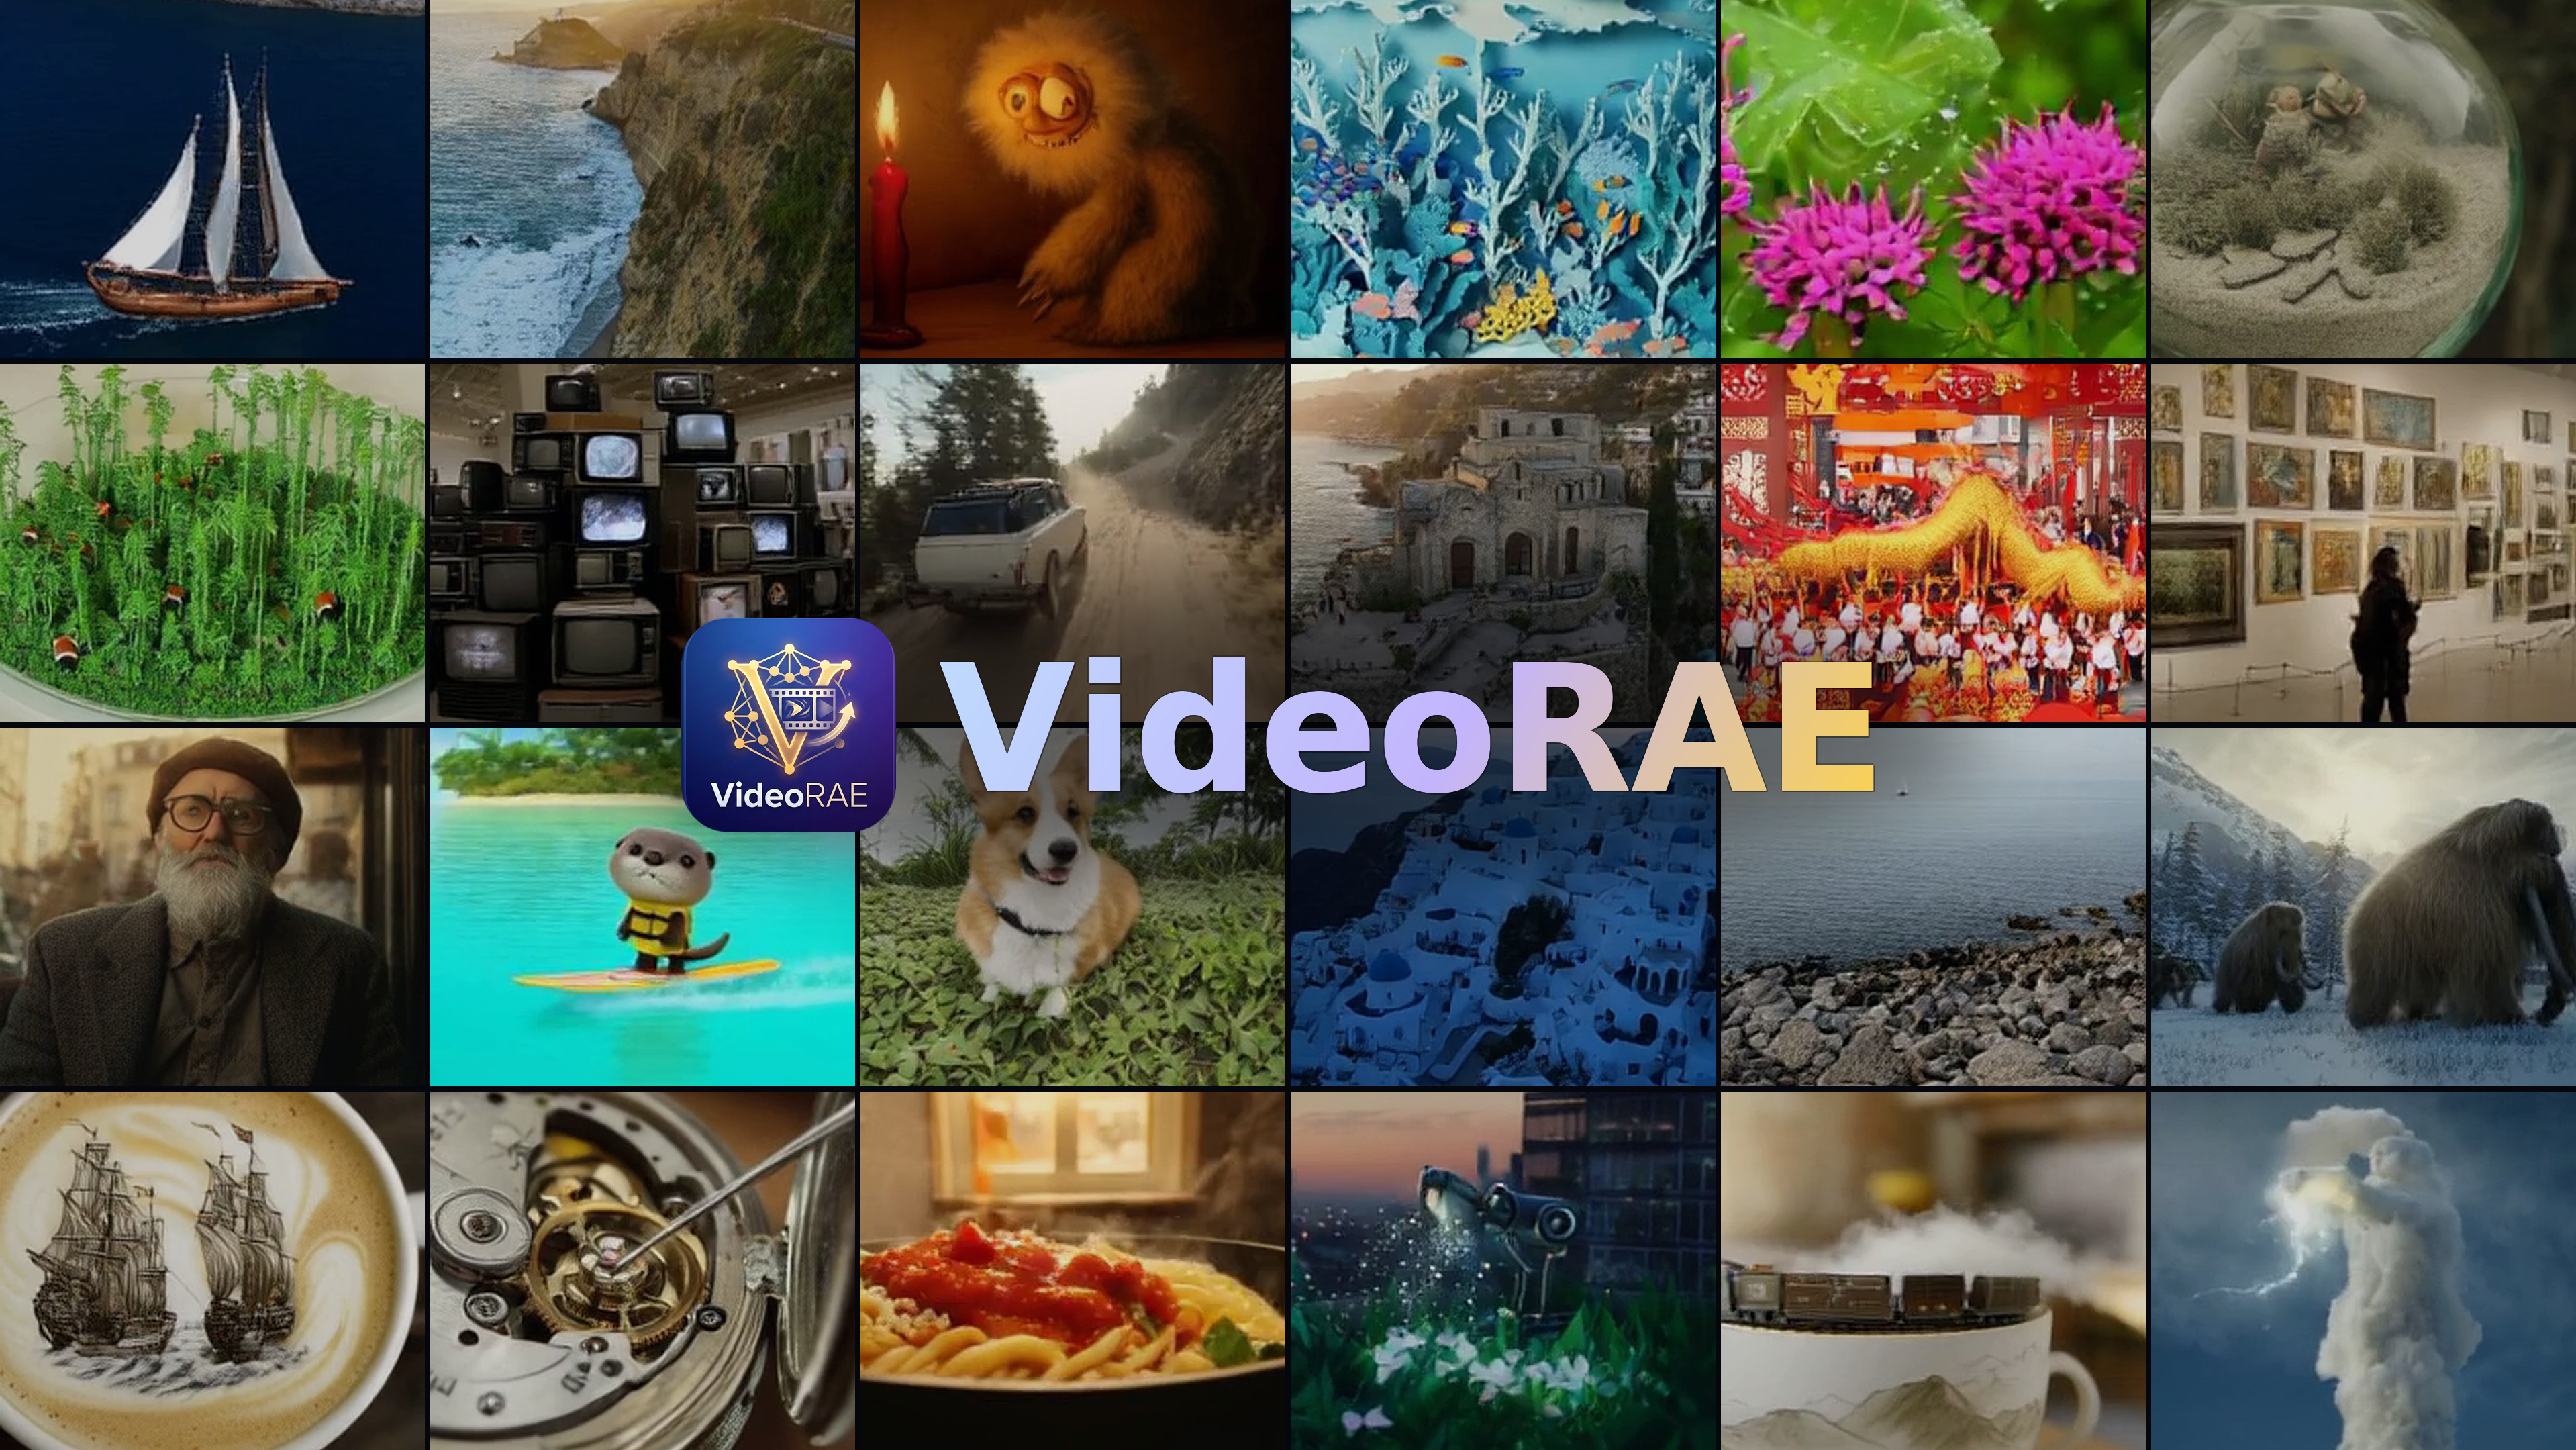
Zhihao Xie*, Junfeng Wu*, Xinting Hu, Junchao Huang, Li Jiang arXiv, 2026 arXiv / code / project page |
|
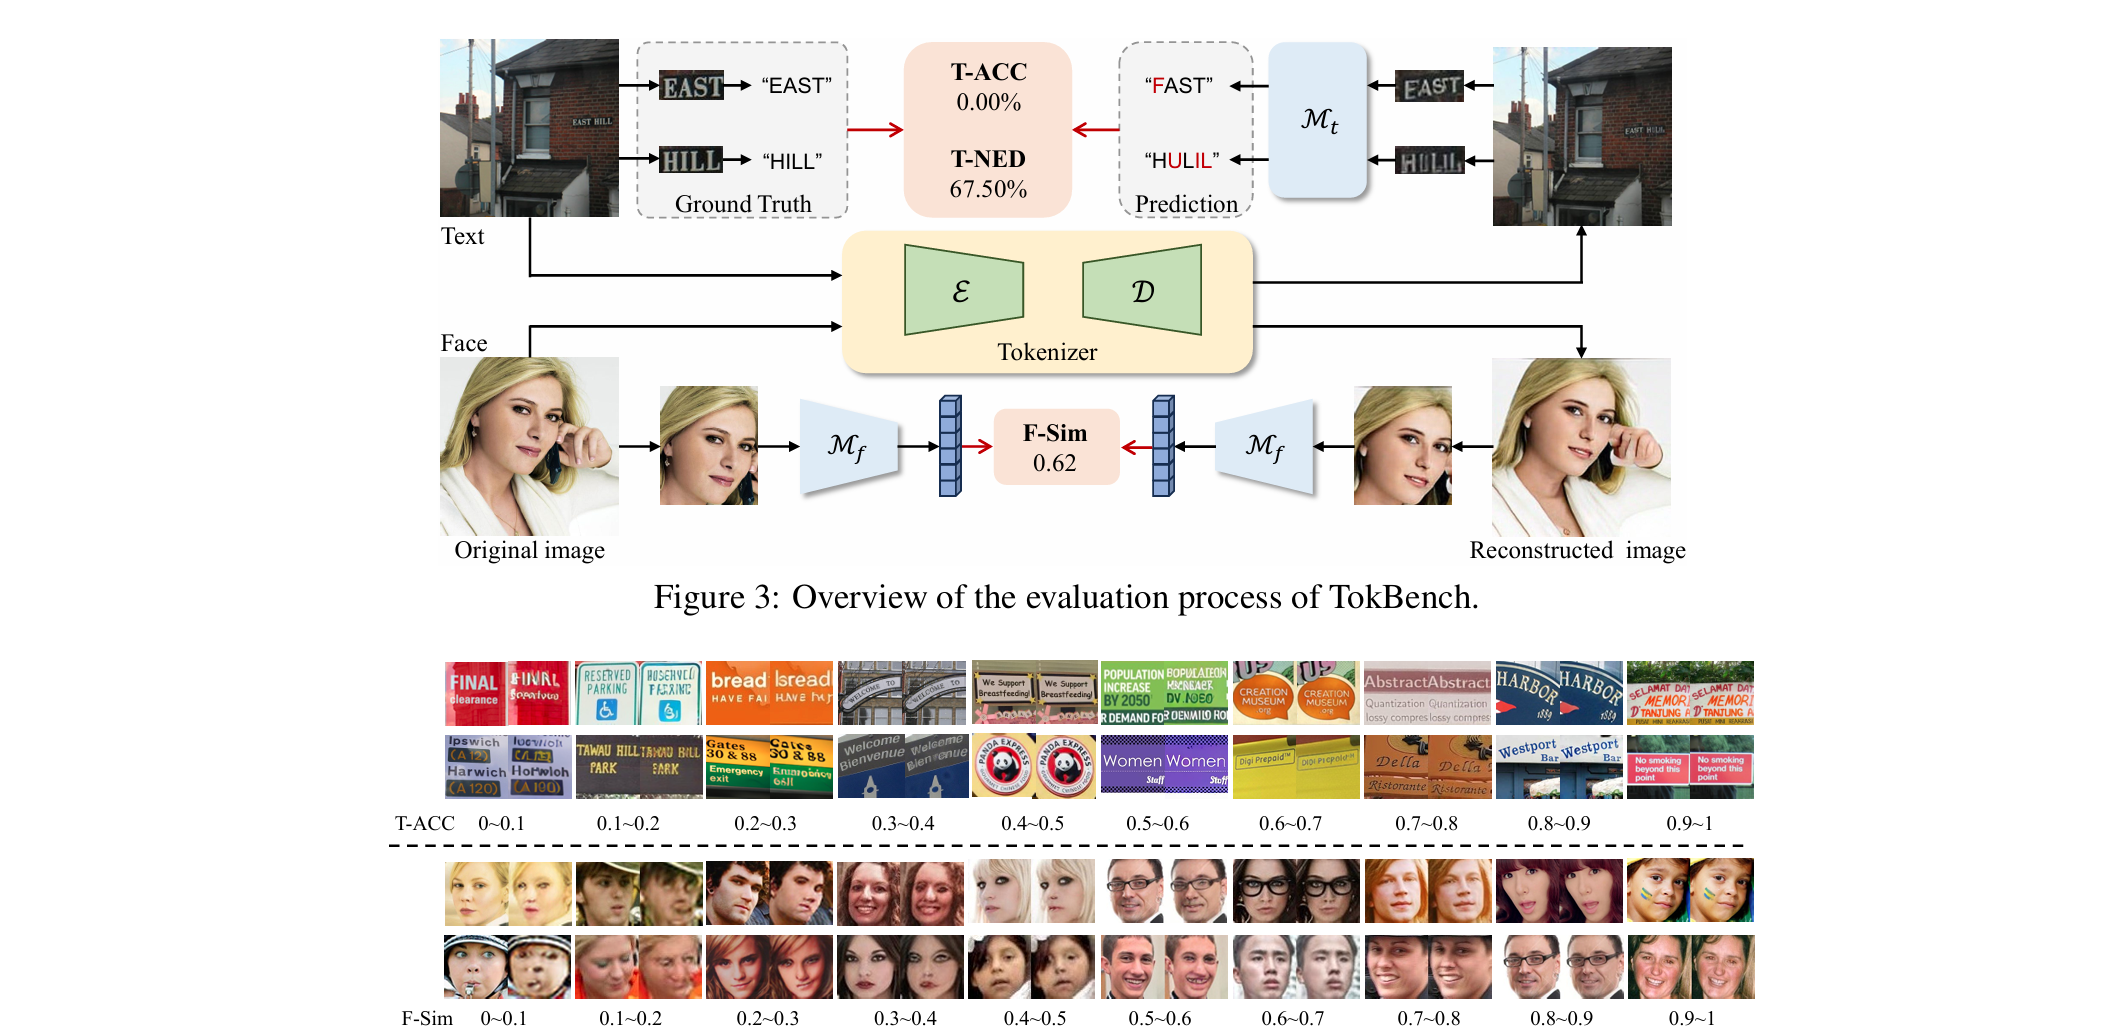
Junfeng Wu, Dongliang Luo, Weizhi Zhao, Zhihao Xie, Yuanhao Wang, Junyi Li, Xudong Xie, Yuliang Liu, Xiang Bai ACM MM, 2026 (Dataset Track Oral) arXiv / project page |
|
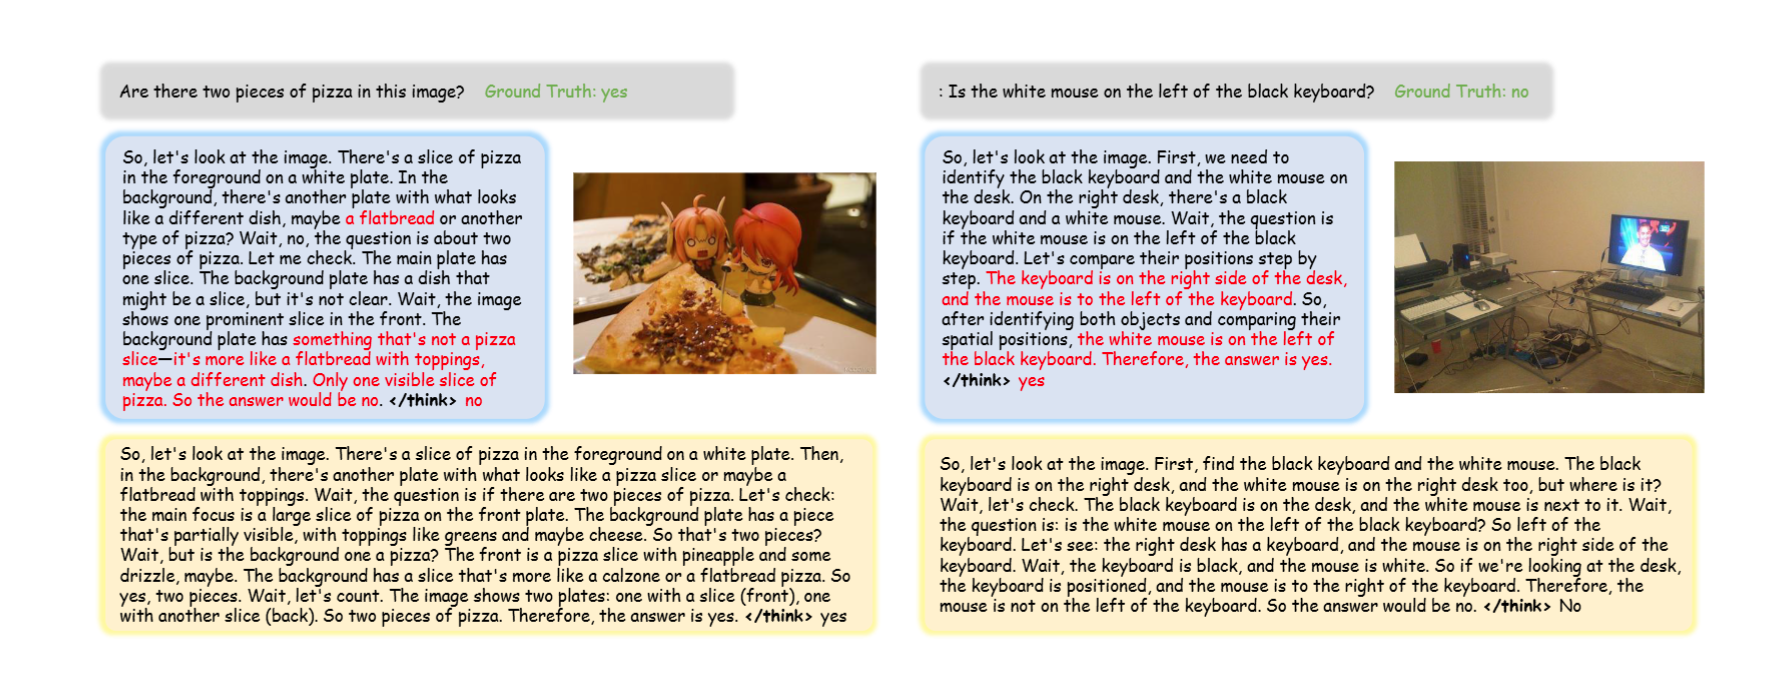
Xiaoye Qu, Yanzhe Wu, Zhihao Xie, Daizong Liu, Wei Wei ACM MM, 2026 |
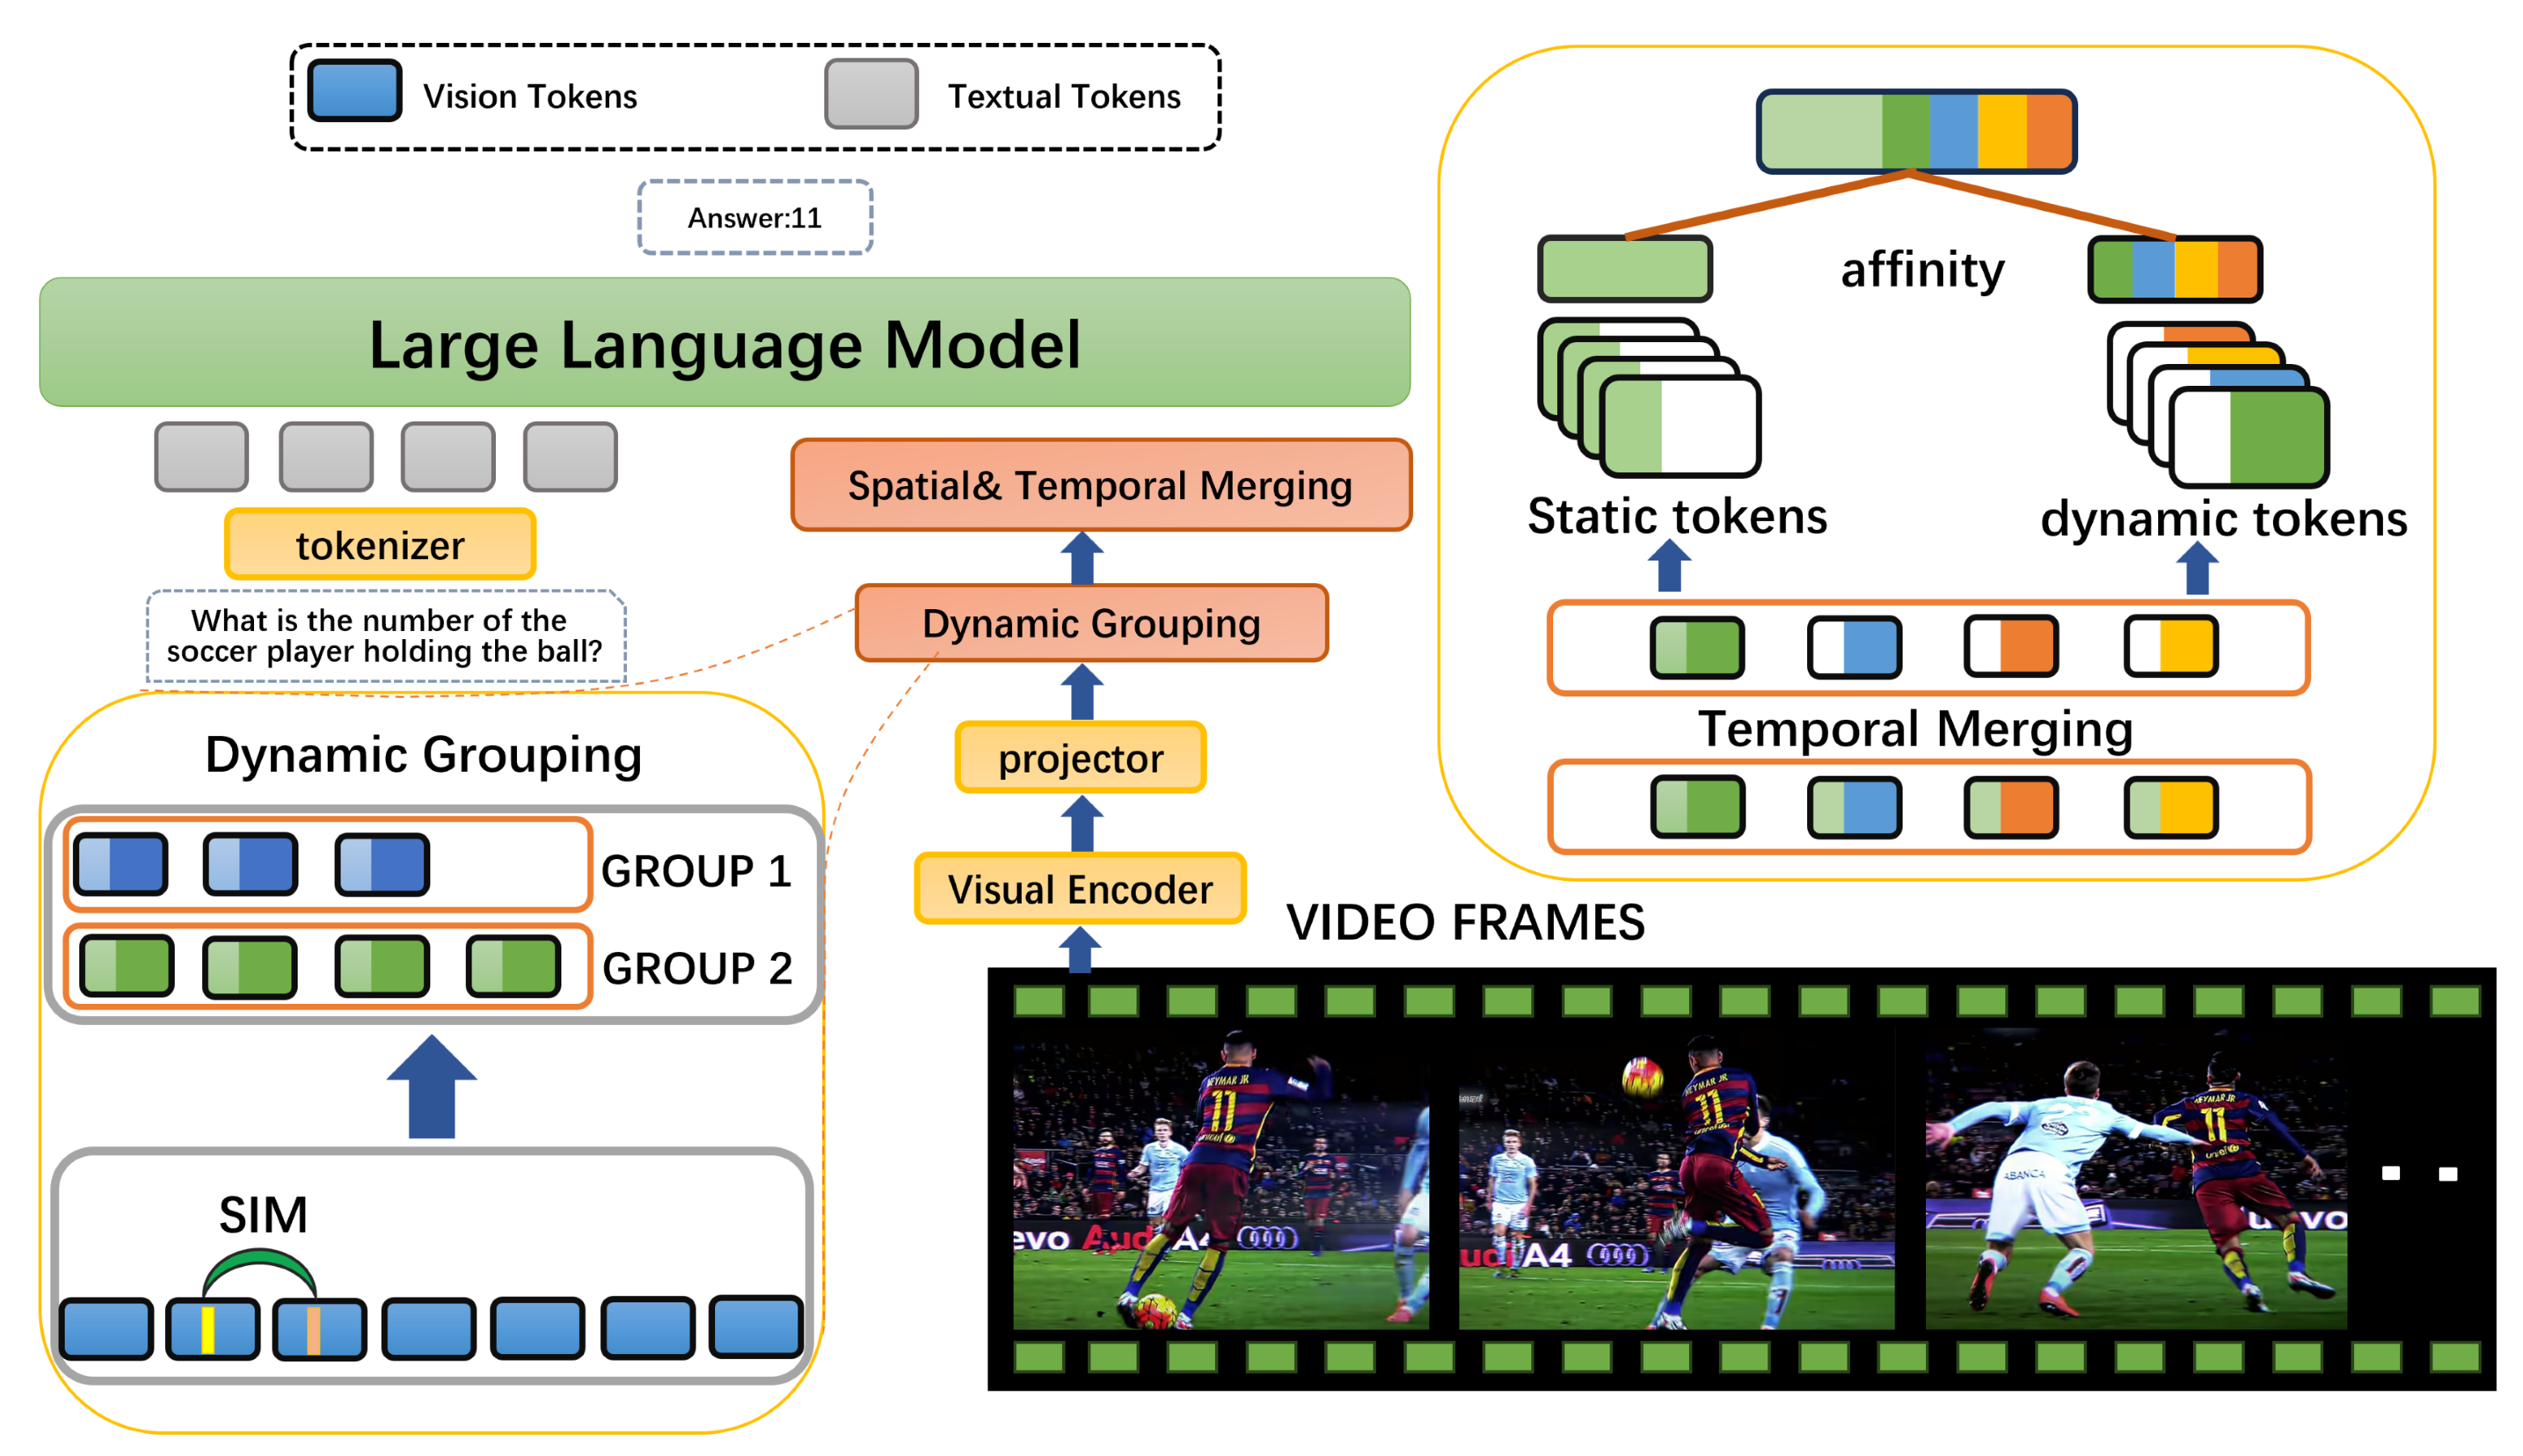
|
Yanzhe Wu*, Zhihao Xie*, Wei Wei ICME, 2026 |
|
Design and source code from Jon Barron's website. |